Where have all the Uber drivers gone?

A seemingly persistent effect of the pandemic on Uber is a 50% decrease in the mobility’s share of revenue (a decrease from a 80% share to less than a 40% share of rides in total revenue). Based on revenue, Uber is now more a delivery company than a mobility company.

This is data centricity extrapolated: a shift from carrying people to carrying objects while solving pretty much the same data-driven optimization problem. The article is from last year but the effect persists as of Q1 2022: Only 37% of the revenue is from carrying people.

Source

Google Imagen

Now that object detection is almost a solved problem, work on the next frontier, text-to-image generation, began to thrive. Google Research’s most recent work on generative models, Imagen, uses text embeddings from a large language model called T5 (similar to GPT3 and OPT175B) to encode text for image synthesis.

Interestingly, the study finds that increasing the size of the language model improves performance more than increasing the size of the image diffusion model. Imagen achieves exceptional similarity between real and synthetic images (measured by the distance metric FID, Imagen achieves a score of 7.27 on the COCO dataset). Human raters confirm the performance of the model.

The paper is nicely written with a much-needed ethics discussion at the end, and full of colorful images. Apparently, Imagen does not perform as well when generating images that portray humans.

Synthetic data generation and image restoration are two common use cases of GANs. I will post a link to one such study on medical images in the comments. Arts and crafts is obvious. I can also think of use cases for fashion and potentially personalization of products in retail. What are some other business use cases?

Source

How does the brain learn mental models?

Interesting read and perspective on modeling the learning in hippocampus and potentially applying the model structure to the design and development of algorithms. Clone-structured cognitive graph (CSCG) uses Markov chains and dynamic Markov compression. So CSCGs form a probabilistic sequence model.

Source

NeuralProphet puts Facebook’s Prophet on steroids using neural networks

Models remain interpretable to the extent that the components of the original function are retained. The authors claim 55% to 92% improvement in accuracy in short to medium-term forecasts, which is impressive if generalizable. Model training time increases 4-fold but prediction time improves 14-fold. Developed on PyTorch so it can be parallelized and deployed on GPUs, potentially to reduce training time. Ported to R but using a Python environment.

Looks promising especially for “AI on the edge” type mobile applications.

Source

Open Pretrained Transformer

Meta AI’s release of Open Pretrained Transformer (OPT-175B), which is on par with OpenAI’s GPT-3 at 175 billion parameters/weights, emphasizes responsible compute and claims one-seventh the computational cost in terms of carbon footprint. Pretrained model weights are free to download (link in the comments). This is good news for open collaboration and better news for the environment.

Source

When reverse causation is more profitable

You may have heard of ESG (Environmental, Social, and Governance) investing. It’s also called “socially responsible investing” when ethics is added to the picture. Public companies are assigned an ESG score, which is a quantification of the social impact. What social impact though? You would probably expect ESG ratings to quantify the societal impact of (not on) a company, right? Well, you’ll be disappointed. “Socially responsible investing” is a misnomer when associated with the ESG ratings, at least those reported by MSCI, a leading provider of the ESG ratings globally.

MSCI basically quantifies the impact of environmental, social, and governance risks on a company’s operations (not the other way around!). In other words, if we rely on ESG ratings while making investment decisions, we may not be doing any social good. We are essentially ensuring that our investments are protected from the environmental, social, and other risks such as climate change. After all, why would we care about the carbon footprint of our investments on the environment as long as profits are good?

MSCI’s plot offers some takeaways on how to generate data and model it. Apparently, measuring reverse causation and packaging it to look like the cause and effect are in the right place can be quite profitable. To be fair, MSCI is explicit about its data generation and modeling process residing in the darkside.

Source

On the proof-of-concept to production gap

A valuable insight on the proof-of-concept to production gap in computer vision that underlines again the importance of context:

“It turns out,” Ng said, “that when we collect data from Stanford Hospital, then we train and test on data from the same hospital, indeed, we can publish papers showing [the algorithms] are comparable to human radiologists in spotting certain conditions.”

But, he said, “It turns out [that when] you take that same model, that same AI system, to an older hospital down the street, with an older machine, and the technician uses a slightly different imaging protocol, that data drifts to cause the performance of AI system to degrade significantly. In contrast, any human radiologist can walk down the street to the older hospital and do just fine.”

Source

99/1 is the new 80/20

An obvious but often neglected fact is the overemphasized value of accuracy as a performance metric. In a two-class problem where 99% of the cases are of 0 (Not a spam email), achieving an accuracy of 99% is as easy as classifying all emails as safe. Sensitivity, specificity, and other metrics exist for a reason.

The story of Waymo, Google’s self-driving car, resembles the value of solving the remaining 1% of the problem where conventional machine learning gets stuck due to the limitations of training data. If 1% of the error turns into a make or break point, one needs to get creative. On a long tail that extends to infinity, walking faster or running does not probably help as much as a leap of imagination.

I must note that it’s not fair to expect an autonomous car to be “error-free” given we do not expect human drivers to perform error-free at the driver license exams and road tests. The two will just make different errors.

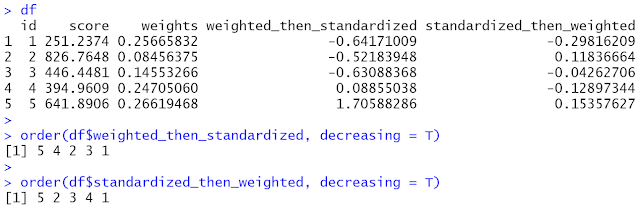
When to normalize / apply weights

To me, this is interesting not because of the lack of transparency in methodology but the potential reason for the rankings to be wrong.

I want to believe that this is a mistake not fraud, but really? Applying the weights before normalizing the scores? And the Bloomberg Businessweek spokesperson says “the magazine’s methodology was vetted by multiple data scientists.”

I have created a quick scenario as a reminder to my former (and current) students (posted in the comments as LinkedIn doesn’t allow here). In the example, the scores are standardized across the five items (which are randomly generated and assigned weights). In the Businessweek rankings, standardization is supposed to be across institutions so that the weights proportionately affect each institution’s score on the corresponding item. Nevertheless, the source of the error is the same. If the weights are applied before normalizing the data, the scores are adjusted by the weights disproportionately. Ranking changes accordingly.