Is AI all you need?

As AI agents win Kaggle competitions, solve math problems, and replace data science workflows, is the data scientist becoming obsolete?

Probably not: most AI breakthroughs are fundamentally iterative, not creative.

While some data science problems rely on trial and error where AI excels, the most critical work still relies on formulating solvable problems out of vague business goals. It requires creatively asking counterfactual questions, deciding on constraints, and applying rigorous reasoning to avoid spurious correlations. This is notably true in causal problems with an optimization component.

The data scientist’s job may be more important than ever, but also different and changing fast. While AI executes tasks efficiently through iteration, it takes human creativity to explain the why and judgment to act on it.

To probe this argument, Duygu Dagli and I will talk with friends leading data science teams about AI in the trenches. We will write up our findings over at Data Duets. You may soon receive an invitation to join us for a quick chat.
Brain activity during LLM-assisted writing

LLMs are bad for learning. When former LLM users are asked to write solo, they show clear evidence of cognitive debt and skill atrophy.

This EEG study tracked brain activity during writing tasks across three experimental groups: Tool-free, LLM-assisted, and Search engine-supported.

Writing on our own stimulates maximum neural activity as it forces memory retrieval, idea generation, linguistic formulation, and self-monitoring.

With an LLM, neural activity plummets. Because the model structures and generates the draft, our brains delegate the heavy lifting. We stop synchronizing thoughts and maintaining a cohesive plan.

The long-term tradeoff is even more striking. Over four months, the LLM group performed worst across the board: neural connectivity, writing originality, and retention. The search engine group performed somewhere in the middle.

LLMs are not tools in the same way as calculators, the Internet, or search engines. None had the autonomy to hijack the mechanics of thinking and planning as LLMs do. I’ve been making this distinction since early 2024 in my talk, “Mind the AI Gap,” and making a case for pre-prompt work while learning.

Sources: MIT Study – “Mind the AI Gap” Talk

Why I type to LLMs

If you’re using LLM agents for your data science tasks, you may feel like you’re the bottleneck. Agents are computationally superior and fast, but if you’re doing serious work, they’re nowhere near autonomous. They need supervision.

To keep up with the pace, you may have added a monitor or two, and turned to speech-to-text to speed up your inputs.

I did both, but my experiment with speech-to-text was short-lived.

Writing is a form of thinking. When I gave up writing for the fool’s gold of efficiency, I also gave up thinking. So it didn’t work out for me. I was quick to get back to typing.

After all, “writing is Nature’s way of showing you how sloppy your thinking is.” — Dick Guindon

This article details a NYT author’s experiment with Wispr, a popular speech-to-text app. It resonated with my experience and prompted this post.

In-context learning for tabular data

For data scientists working on tabular data, which is still most of the data science world, Google’s TabFM is a nice solution using transformers (thankfully not LLMs).

TabFM promises to break the tedious cycle of endless hyperparameter tuning and feature engineering in ensemble methods like XGBoost. Instead of a manual training loop, TabFM treats tabular prediction as in-context learning: it ingests the entire dataset as a single prompt and predicts outcomes in a single forward pass. Clearly, the context window becomes the primary bottleneck as the dataset grows.

My day-to-day is mostly causal inference, with some projects using predictive models. Also interesting to me here is how the team solved the training problem: they pretrained the model on hundreds of millions of synthetic tables generated using Structural Causal Models.

This aligns neatly with our posts at Data Duets, specifically around the value of using transformers to generate datasets and our broader Augmented Data Science framework.

Source

Gambling on AI in stock markets

Trading AI stocks is starting to look indistinguishable from online gambling. Like sports betting and prediction markets, it has the necessary ingredients:

  • Intermittent Reinforcement: The unpredictable dopamine hit of daily price swings.
  • Social Reinforcement: High-pressure FOMO when “everyone is doing something.”
  • Gamification: Onboarding high schoolers to apps with $14 sign-up bonuses.

[…] Na and her co-workers joke they should sell their underwear to buy more shares. “Even friends who have never touched stocks are getting into it,” Na said. “Everyone’s doing something.”

Accelerating demand for AI-related goods has spurred investors—in Taipei, taxi drivers trade stocks mid-ride—and boosted salaries.

More than 180,000 trading accounts for children 18 or younger were created in the first three months of the year at Toss Securities, a South Korean brokerage. The accounts require parent approval to open and allow children to trade on their own. A recent promotion offered to deposit $14 into new accounts opened by high-school students.

Let’s see how this one will end.

Source: WSJ (gift link)

New post at Data Duets: Data cleaning agent

We have released our newest skill for the Augmented Data Science framework: a data cleaning agent.

Why do we need a skill for data cleaning? Because data cleaning isn’t just an execution task, it requires explicit modeling decisions.

In this series, we are studying the best use of AI in data science. Along the way, we develop and test skills with the ultimate goal of combining them using an orchestrator agent. Our goal is not automation, but to define the roles: data scientists set the intent, target, and method, while LLM agents execute.

Check out the post to see how we tested this skill on a large Amazon purchase dataset for customer behavior modeling (and how it successfully avoided data leakage).

Link to the post

New chapter in Causal Book: Oh my! Matching can make DID worse

Just published the latest Causal Book chapter for data scientists.

Matching is controversial in diff-in-diff use cases, and for good reason. In this chapter, we review two studies to delve into the details and understand the optimal decision, which is arguably not to match the treatment and control groups at all.

Causal Book is an interactive resource for applying modern methods and tools to causal inference. It follows a nonlinear path, unlike a traditional book. Because of this unique structure, the new chapter doesn’t have data just yet (as the preceding chapters are still in progress), so expect an update down the road.

Link to the New Chapter

Cal State going all in on AI

So the California State University system was the largest single-institution deployment of ChatGPT in the world. Last year, it paid OpenAI $16.9 million. That’s quite a pivot in resource allocation. This is an interesting story with rich anecdotes to learn from.

At San Jose State — the oldest public university in the California State University system — evidence of the shift toward A.I. is evident across campus. The university now has an A.I. librarian, and its main library features a new A.I. Center for Civic and Social Good. The business school runs an A.I. boot camp for high school students; the campus career hub is sponsored by Adobe; A.I. literacy training is an orientation requirement and, last year, an A.I. agent helped coordinate commencement logistics.

…

Will these graduates be ahead of the curve in the new A.I. economy, or robbed of a chance to hone their critical thinking skills?

Source: NYT Magazine (gift link)

Token maxxing

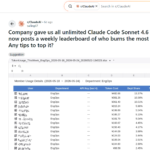
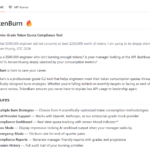
Image 1 shows an AI management problem. Image 2 is a solution: token maxxing.

When employees are judged purely by a number, they will optimize for the number, even if it burns the business down around them. On the other hand, businesses often measure only what’s easy to put on a spreadsheet and assume that everything else follows suit (or doesn’t matter).

This contradiction looks like a perfect example of a perverse incentive combined with the streetlight effect.

Sources: Reddit thread – TokenBurn on GitHub

Papers with Code is back

Remember Papers with Code?

Meta acquired it years ago and shut it down last year. Now, the open-source team at Hugging Face seems to have brought it back. While it’s not exactly the same (agents have fully taken over the curation), it still looks like a useful repository for tracking the latest AI work.

New project link: https://paperswithcode.co